Building a global object store on FoundationDB
This post is an edited transcript of an in-person talk on June 16th. Parts have been re-organized for your reading convenience.
Hello everyone! I'm Himank, the CTO and a co-founder of Tigris Data. Tigris is a globally distributed object store.
Tonight other speakers talked about the scale of data involved with training foundation models. Something has to hold all of that data. That's the part that Tigris works on.
My talk will be focusing more on the metadata storage of Tigris, like how we are using FoundationDB in our whole stack to power our metadata.
What is Tigris?
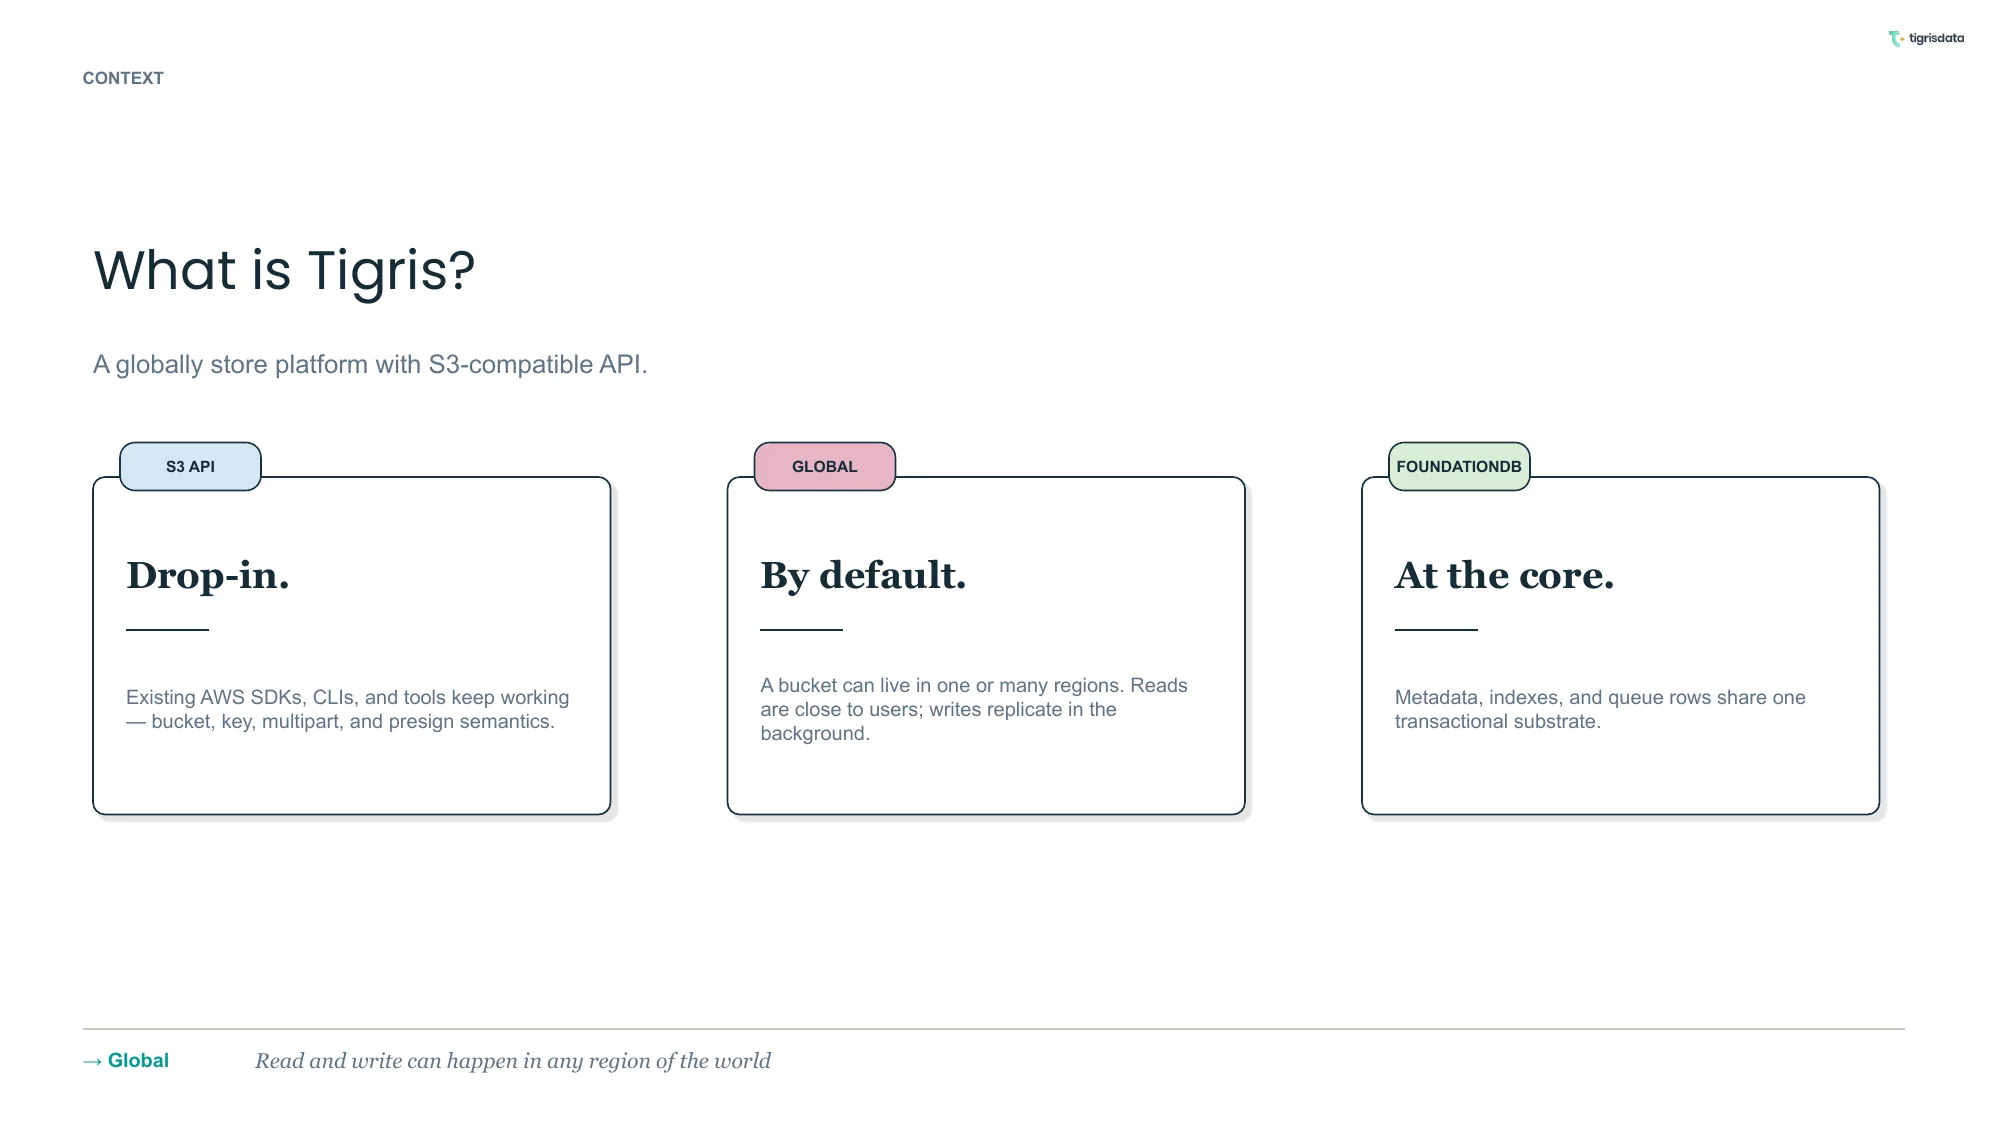
First, Tigris is a global storage platform that is fully S3 compatible. From a user perspective you don't need to do any code changes. It will simple work with your existing S3 stack. All you need to do is switch from your existing S3-compatible provider to Tigris and it will just work.
Second, we're rethinking the object store from the ground up. Traditionally object storage is known for cold caching. We're focusing on reframing object storage as global infrastructure. How can we provide an object store as global infrastructure? Users should not need to think about replication or caching. We want users to get a bucket, upload data, and the data is available everywhere in the world.
Finally, we want to make the data globally available and optimize the read latency so that it doesn't matter where your compute is located. Tigris makes your data follow your compute so you can pick from any compute or GPU provider without worrying about your data being slow.
In order to make Tigris global by default, we're using FoundationDB. We store all object metadata, users, and buckets in FoundationDB.
Read and write in any regions
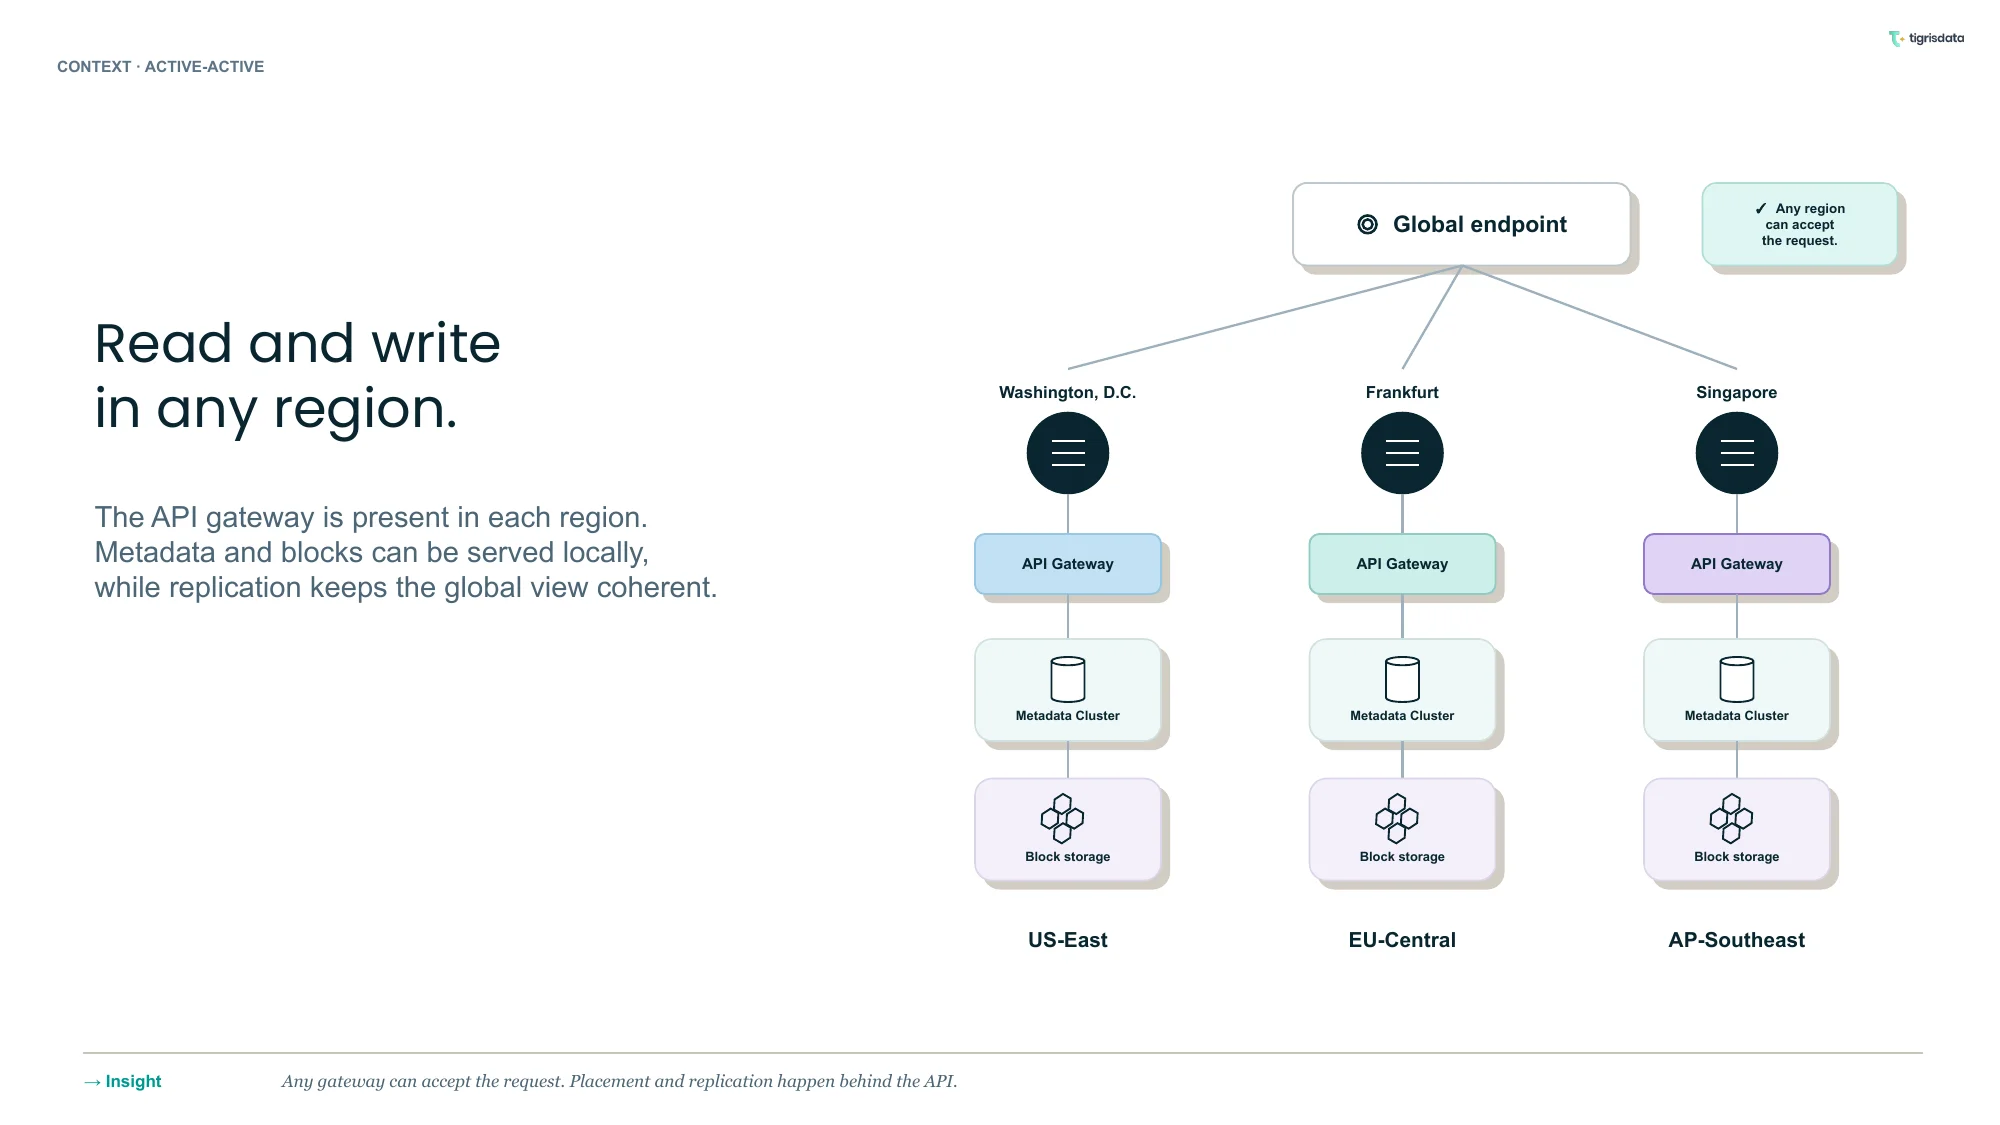
When we were designing our system, we were thinking a lot about how we can make the components loosely coupled, but have an aggregated architecture where storage is decoupled from other components. This would let us scale any of these components independently.
For example, in each region we have our gateway, caches, metadata clusters, block storage backends, and asynchronous queue workers. All of these services can be scaled independently based on our needs, running on metal. The gateway and workers are stateless, everything else is where the state lives.
So the obvious question at that point is what should we use for our metadata storage? Metadata is very important. Tigris is mostly exciting ways to arrange metadata with boring ways to store data.
Why FoundationDB?
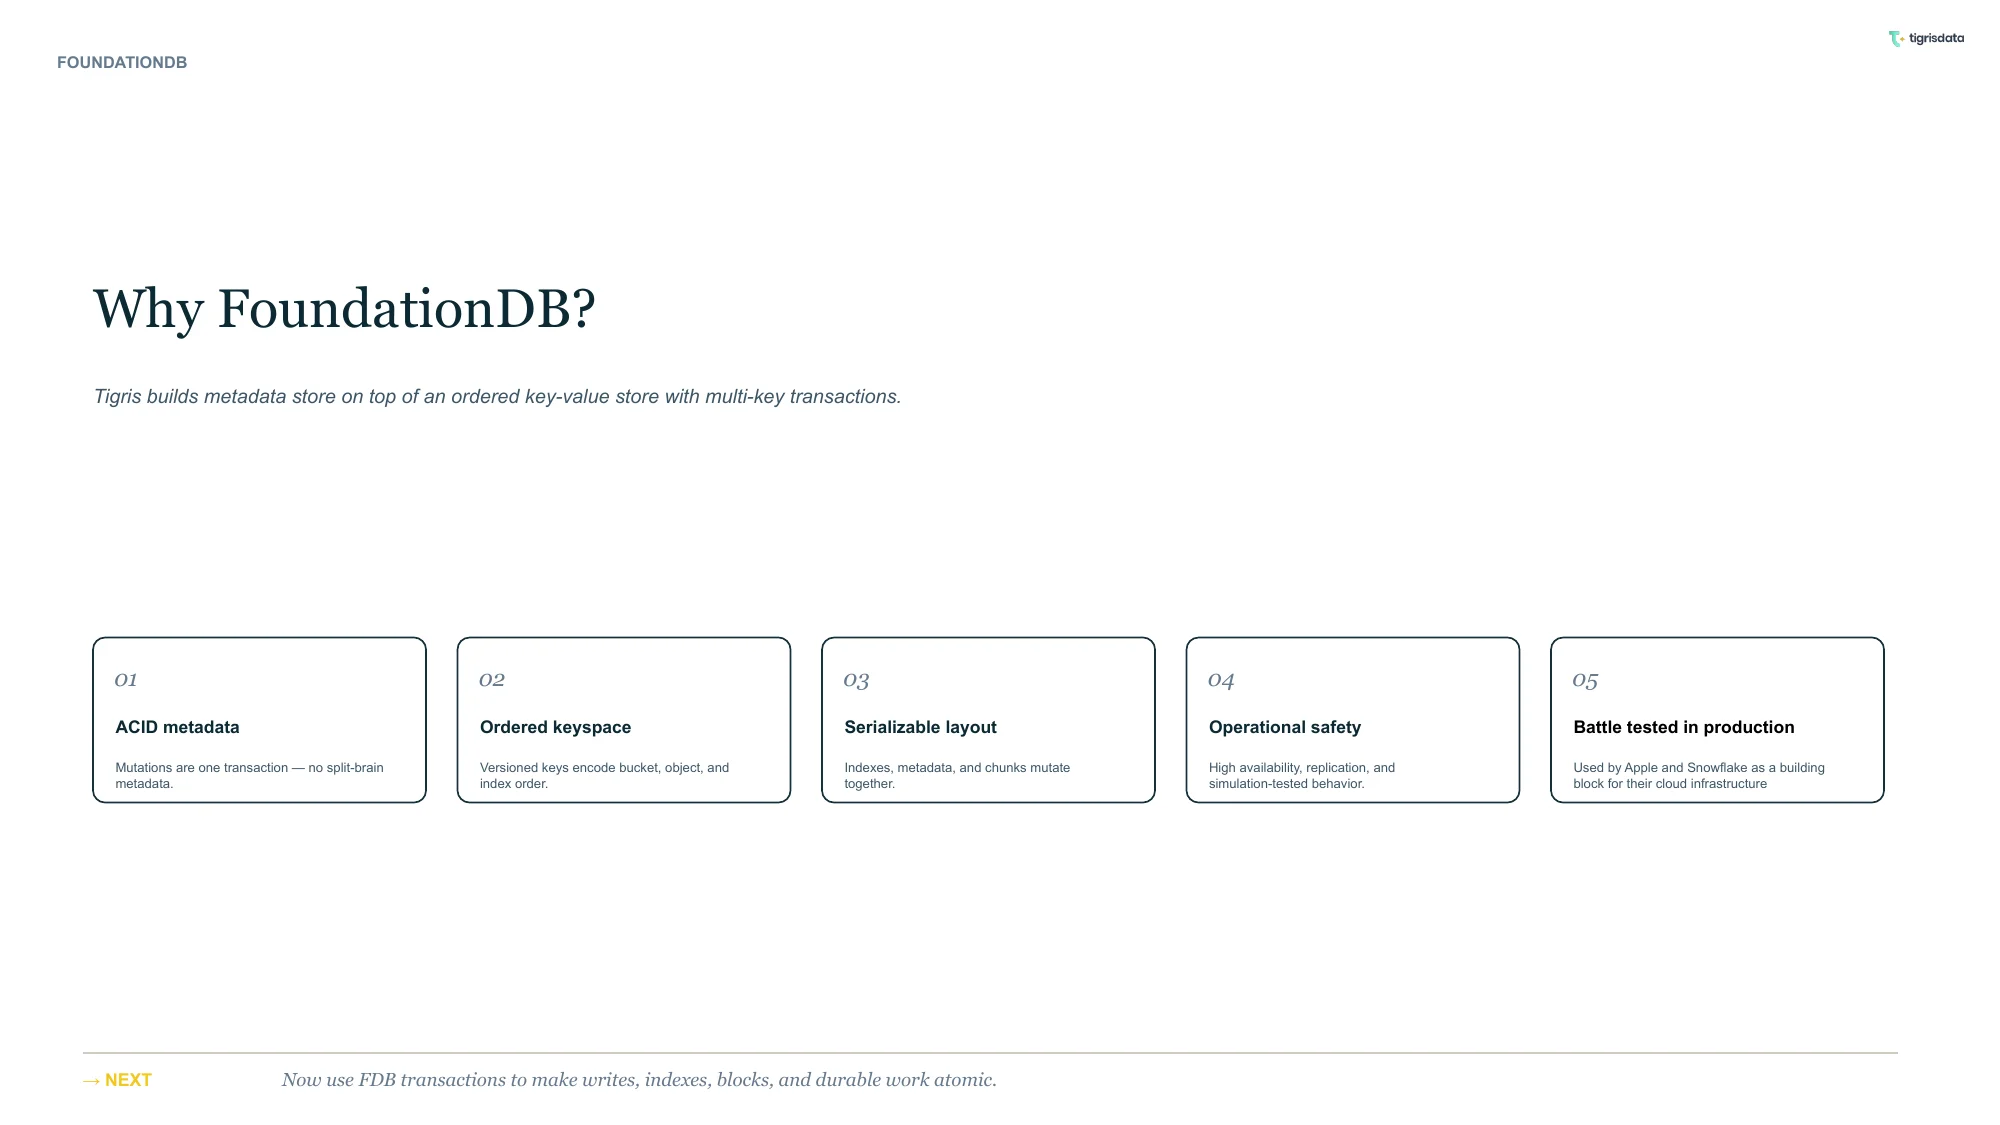
There were a few options, either we built something on our own or used something from outside. We picked FoundationDB for a few reasons:
- ACID metadata: In FoundationDB, mutations are one transaction. There is no possibility of having split-brain metadata.
- Ordered keyspace: FoundationDB keys have an inherent order, so versioned keys encode bucket, object, and index order.
- Serializeable layout: Indices, metadata, and chunks mutate together.
- Operational safety: FoundationDB is high availability almost to a fault, replicates cleanly without human intervention, and has simulation testing to the level that Aphyr didn't even bother to evaluate it.
- Battle-tested in production: FoundationDB is used by companies like Apple and Snowflake as the foundation of their cloud infrastructure.
At some level, it's best to think about FoundationDB as a distributed filesystem that handles the hard parts for you: sharding, consensus, replication, and transactions. You then get to build your own layer on top of it. FoundationDB doesn't provide a schema, table layout, or indices. That's in the part you are expected to provide.
FoundationDB at the core
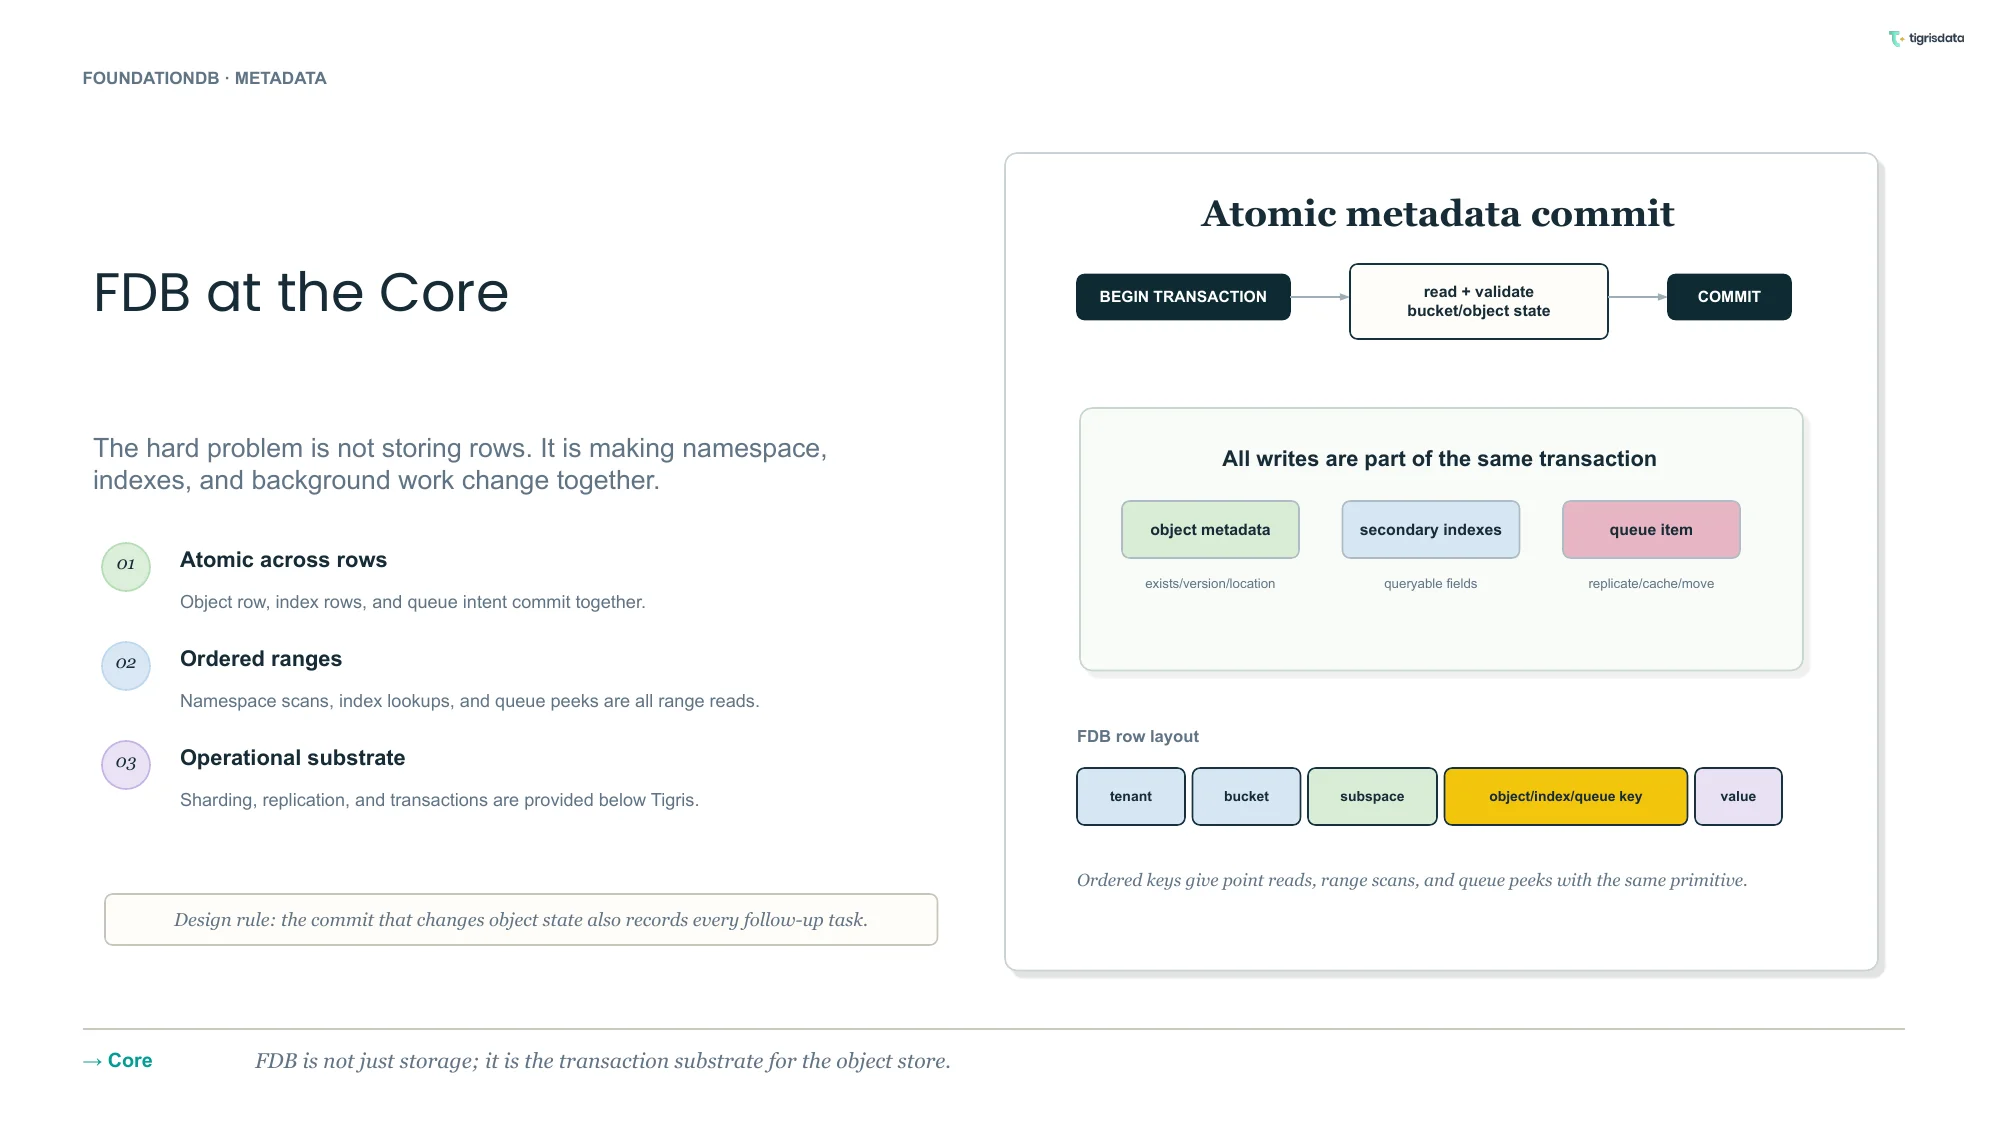
Once we committed to FoundationDB we had to make a few changes to how we did things. In FoundationDB it's impossible to read or write data without a transaction. This sounds like a lot of overhead until you realize what it gives us. A single object write usually involves reading the current state, updating the new state, and then enqueueing the object for replication and indexing.
We also had to design our row layout, so we designed one that lets us support efficient scanning for our users:
key · lexicographic, one contiguous range per subspace value┌──────────┬──────────┬────────────┬────────────────────────────────┐ ┌────────────────┐│ tenant │ bucket │ subspace │ object / index / key │ │ value │├──────────┼──────────┼────────────┼────────────────────────────────┤ ├────────────────┤│ t_9f3a │ photos │ obj │ 2026/08/img_001.jpg │ ──▶ │ manifest ptr │└──────────┴──────────┴────────────┴────────────────────────────────┘ └────────────────┘└─────────────────── one FDB key, tuple-encoded ────────────────────┘
This lets us serve efficient queries for a single bucket. We don't need to worry about sharding or multi-hit transactions. This comes by default with FoundationDB.
What do writes do?
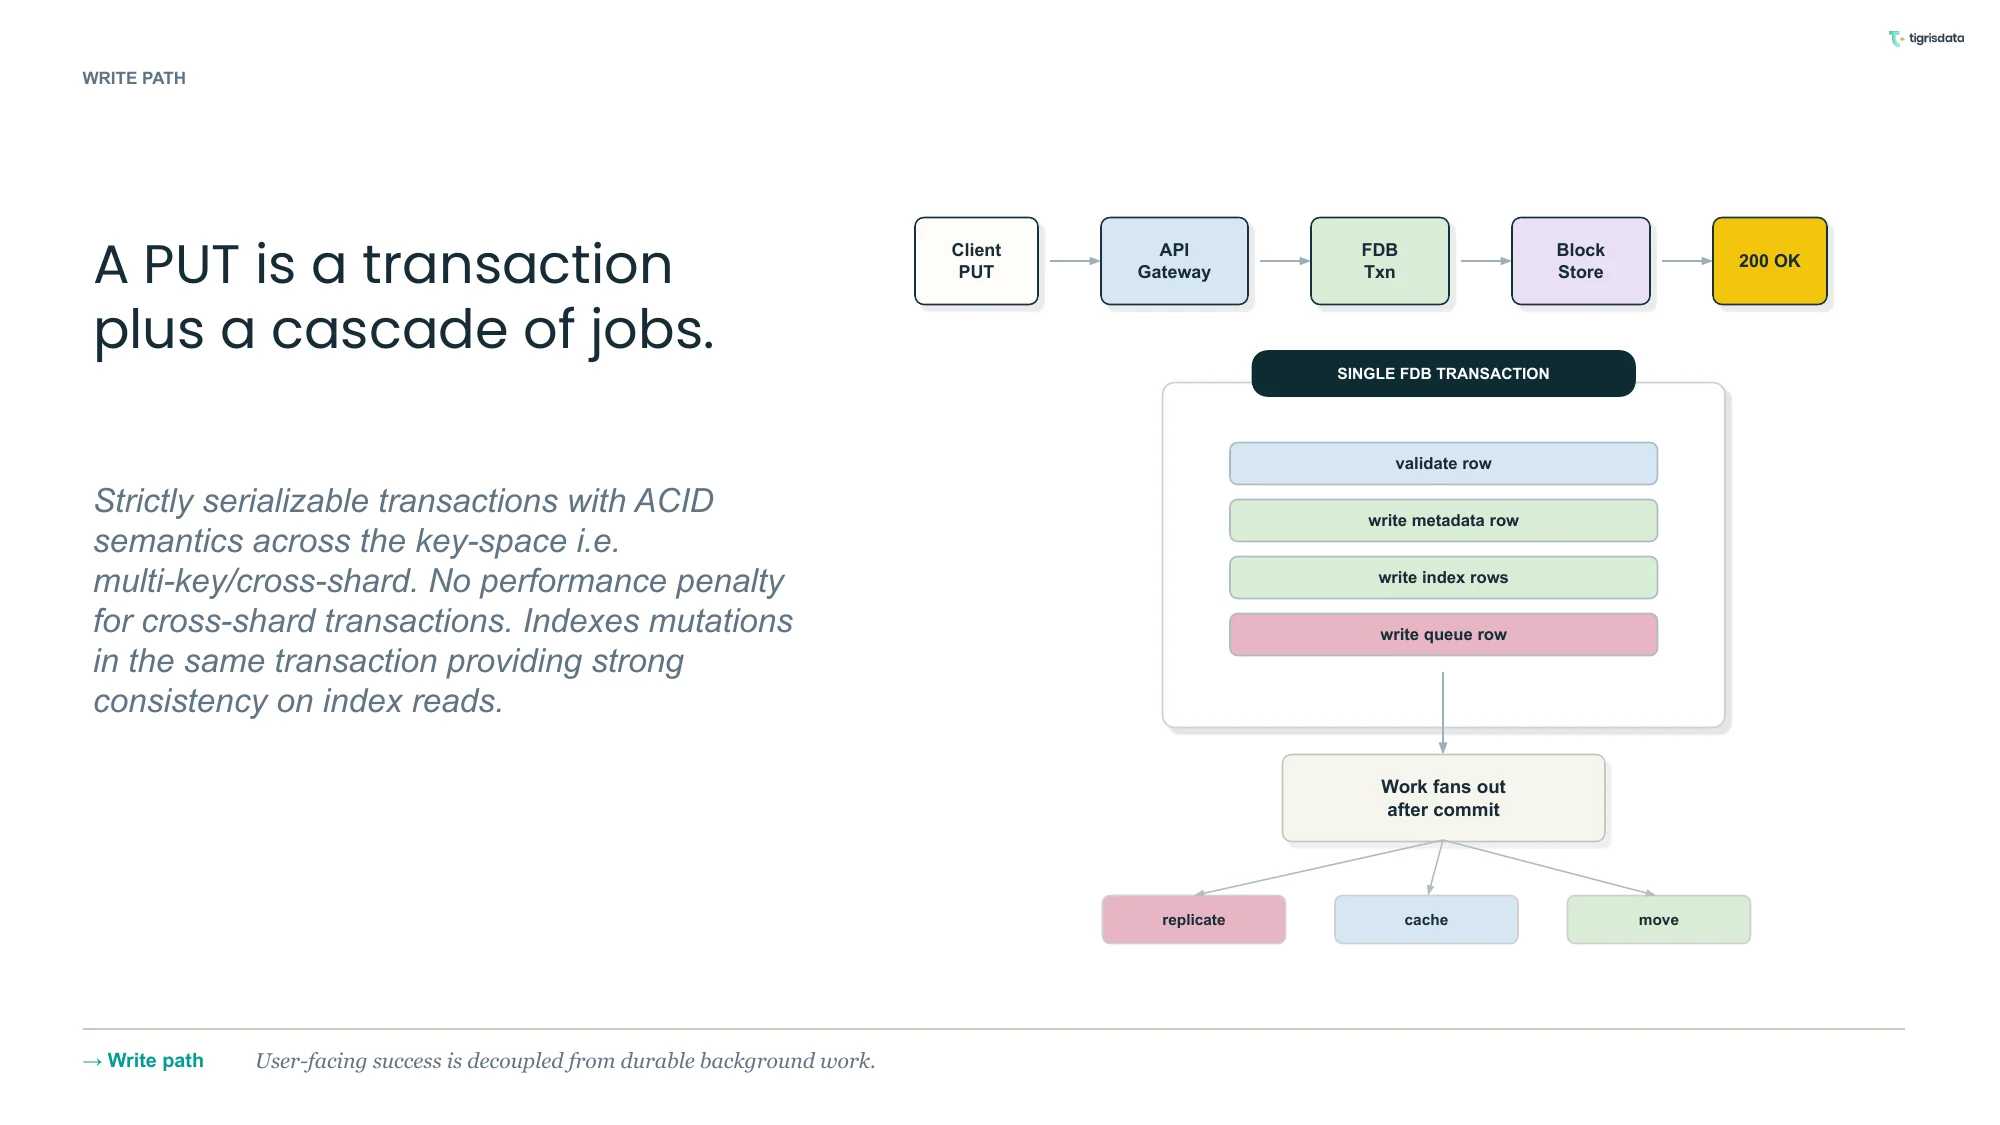
So what does a PUT look like? As I mentioned before, we use strictly ACID transactions. A single write for us reaches the layer and we break the write into the data block and the metadata. We write the block into block storage first and then we start a FoundationDB transaction. In this transaction we write object metadata and then update our indices along with that metadata. We also have a bunch of other work that needs to be done after a write completes, so we write to the queue in the same transaction.
What is that other work? Tigris is global, so we have to replicate the data globally. We also have caches that need to be updated, so we have asynchronous queue workers that can handle all this. But to run that async machinery we need to have some kind of task mechanism that we do as part of our write.
Normally you end up having to juggle two transactions: one to your database and another to your message queue. We implemented our message queue in FoundationDB using the fact that both FoundationDB and time are ordered. We don't have to run a distributed transaction between two systems or add expensive recovery logic to ensure tasks don't get lost. Either everything commits or nothing commits, which is one of the best parts of FoundationDB.
Once this write commits and we know that any work items have been added to their queues, we return to the user and the transaction completes successfully.
How do we resolve GETs?
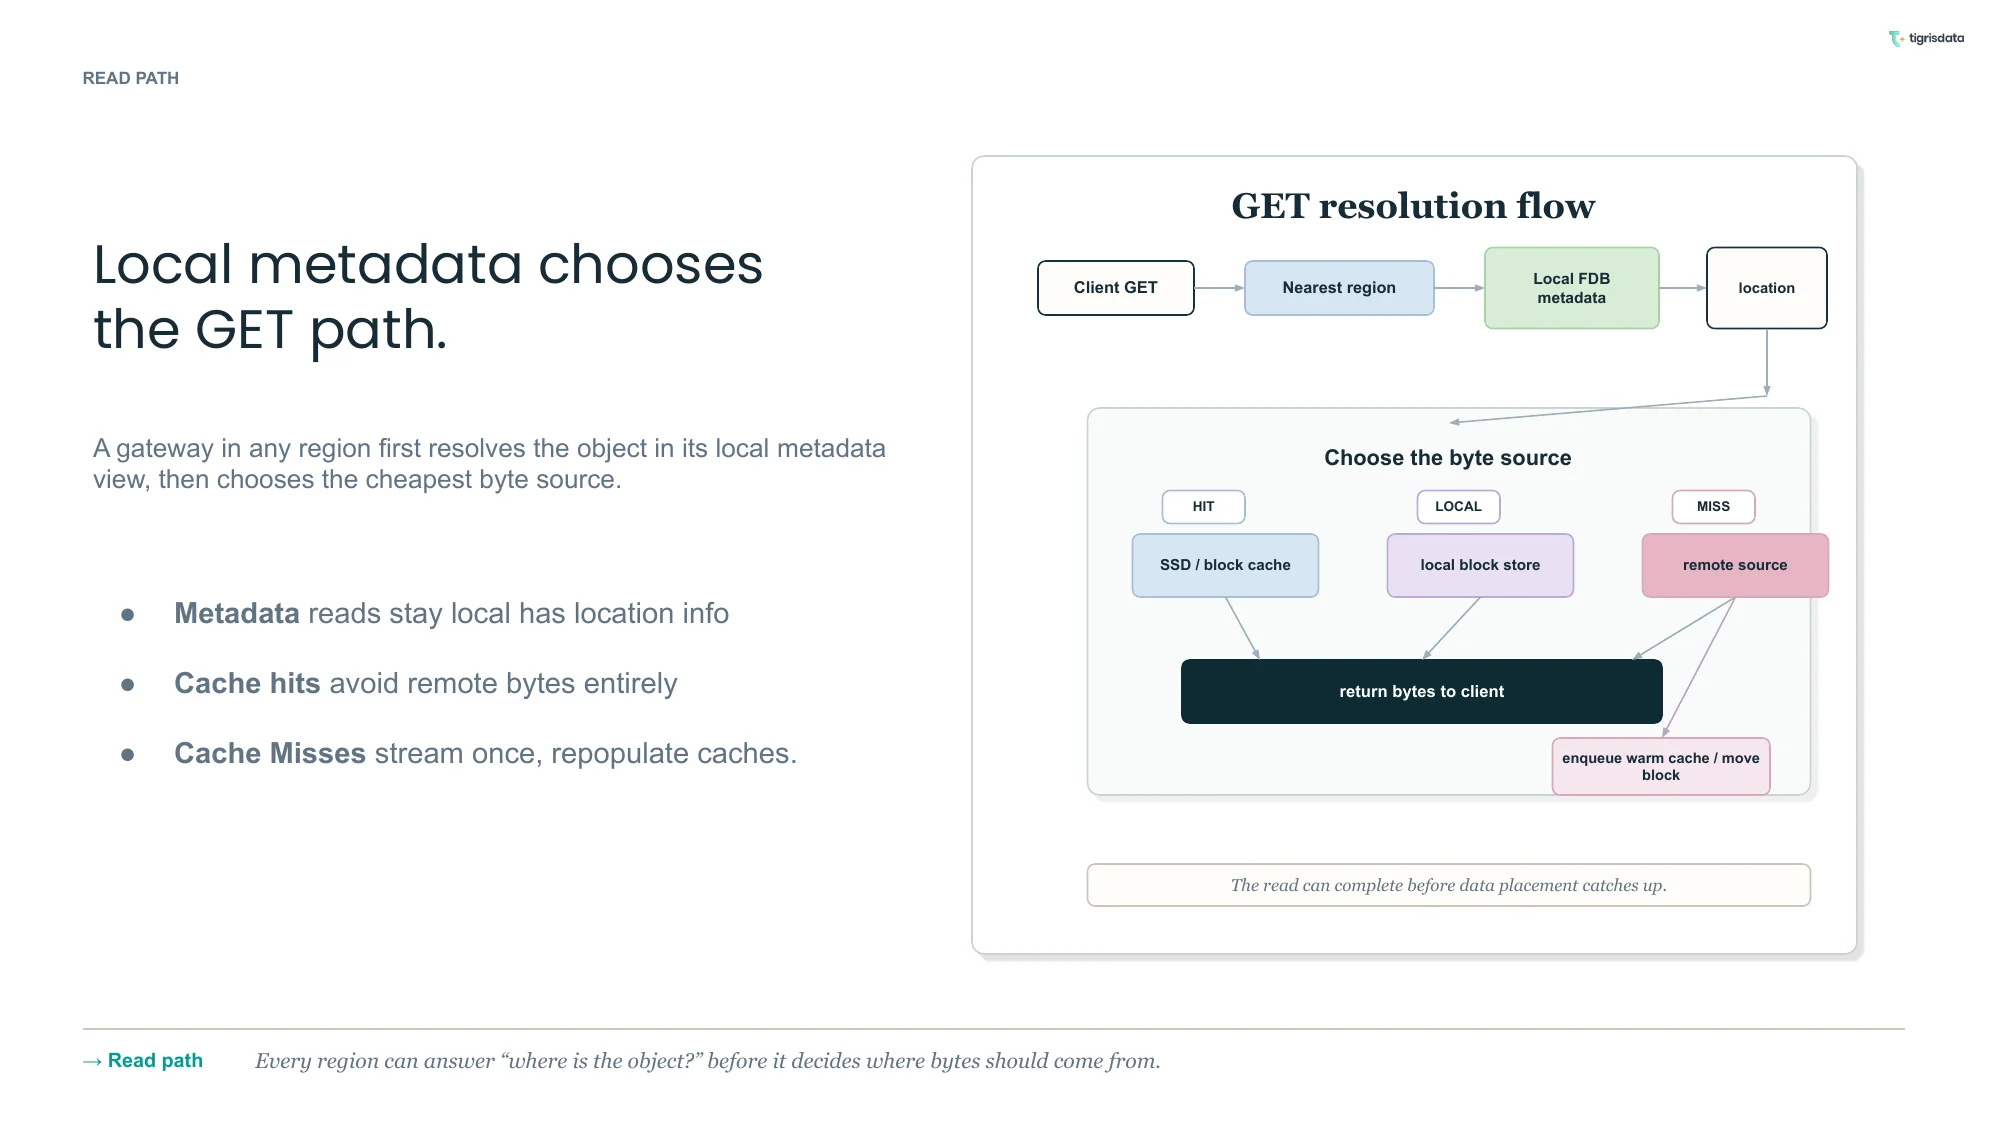
How do we ensure that objects can be served from any region when the data may be stored in any other region?
One way to think about Tigris is that it's a multi-tier cache that has endpoints all over the world. When users request objects, a combination of anycast routing and geo-DNS make sure that requests go to the closest datacenter. All our metadata is eagerly replicated between FoundationDB clusters in each region, and that metadata includes where the object actually lives.
┌────────────┐ ┌────────────────┐ ┌────────────────────┐ ┌────────────┐│ client GET │──▶│ nearest region │──▶│ local FDB metadata │──▶│ location │└────────────┘ └────────────────┘ └────────────────────┘ └──────┬─────┘choose the byte source │┌───────────────────────┬───────────────────────┬──────────┘▼ ▼ ▼┌─ HIT ──────────────┐ ┌─ LOCAL ────────────┐ ┌─ MISS ─────────────┐│ SSD / block cache │ │ local block store │ │ remote source │└──────────┬─────────┘ └──────────┬─────────┘ └──────────┬─────────┘│ │ ├──▶ enqueue warm-cache / move└───────────────────────┬───────────────────────┘▼┌──────────────┬─────────────┐│ return bytes to client │└────────────────────────────┘// the read can complete before data placement catches up
If the object is in the local block cache, that gets served directly to the client. If the object is in the local block store, that also gets served directly to the client. If the data isn't stored locally, Tigris needs to fetch it from another region. In order to do that it reverse proxies the read to the block store in the region where the data actually lives. Since a user requested it, we enqueue a block store replication job so that the next GET request is faster. This makes future GETs much more efficient.
This is not the case when you are using a dual-region bucket, which lets you confine objects to a single region for policy or compliance reasons.
Our queueing system
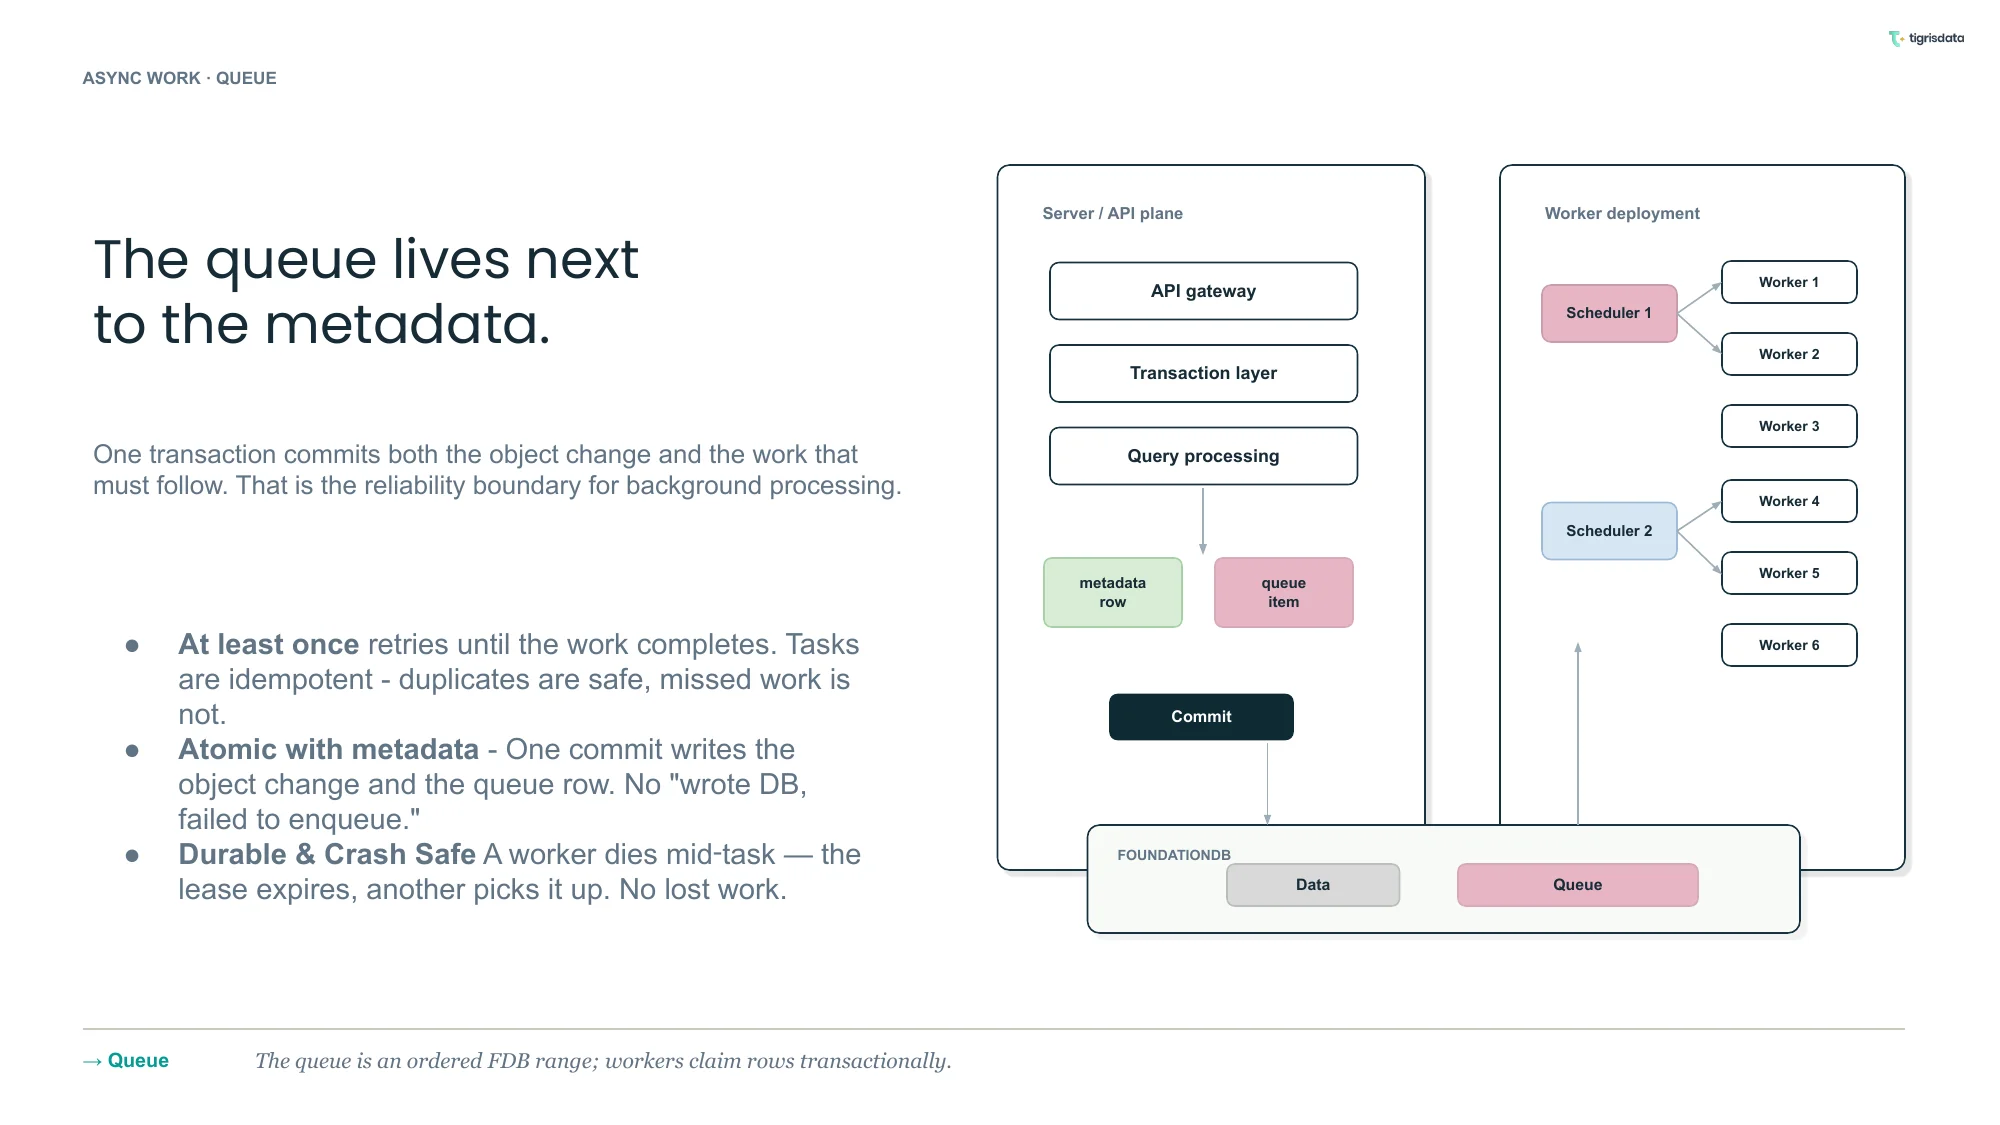
We built our own queueing system on top of FoundationDB by following what Apple did with their QuiCK: A Queueing System in CloudKit paper. The queue is just an ordered FoundationDB keyspace. Workers claim rows transactionally. The work itself happens asynchronously outside of a transaction, but the coordination layer is FoundationDB.
Building our own queue on top of FoundationDB lets us ensure that we have ACID semantics when we add tasks to the queue. This also lets us ensure that we have at-least-once semantics for tasks in the queue. We cannot lose tasks because they are always present in the FoundationDB queue.
These task writes are atomic with the metadata so either an object writes successfully with its tasks and metadata or nothing happens. No in-between state. An interesting side effect of this is that our workers can crash all they want. Another worker will pick the task up without any human intervention.
┌─ server / API plane ───────────────────┐ ┌─ worker deployment ──────────────────┐│ ┌────────────────────────┐ │ │ ┌─────────────┐ ┌──────────┐ ││ │ api gateway │ │ │ │ scheduler 1 │──┬───▶│ worker 1 │ ││ └────────────┬───────────┘ │ │ └─────────────┘ │ └──────────┘ ││ │ │ │ │ ┌──────────┐ ││ ▼ │ │ └───▶│ worker 2 │ ││ ┌────────────────────────┐ │ │ └──────────┘ ││ │ transaction layer │ │ │ ┌──────────┐ ││ └────────────┬───────────┘ │ │ │ worker 3 │ ││ │ │ │ └──────────┘ ││ ▼ │ │ ││ ┌────────────────────────┐ │ │ ┌─────────────┐ ┌──────────┐ ││ │ query processing │ │ │ │ scheduler 2 │──┬───▶│ worker 4 │ ││ └────────────┬───────────┘ │ │ └─────────────┘ │ └──────────┘ ││ ┌────┴──────────┐ │ │ │ ┌──────────┐ ││ ▼ ▼ │ │ └───▶│ worker 5 │ ││ ┌──────────────┐ ┌─────────────┐ │ │ └──────────┘ ││ │ metadata row │ │ queue item │ │ │ ┌──────────┐ ││ └───────┬──────┘ └──────┬──────┘ │ │ │ worker 6 │ ││ └─────────────┬─┘ │ │ └──────────┘ ││ ▼ │ │ ││ ┌──────────┬─────────┐ │ │ ││ │ commit │ │ │ ││ └──────────┬─────────┘ │ │ ││ │ │ │ │└───────────────────────┬────────────────┘ └─────────┴────────────────────────────┘│ ▲▼ │┌─ FOUNDATIONDB ────────┬──────────────────────────────┴─────────────────────────────┐│ ┌──────┬─────┐ ┌────────┴───────┐ ││ │ data │ │ queue │ ││ └────────────┘ └────────────────┘ │└────────────────────────────────────────────────────────────────────────────────────┘// one transaction writes the metadata row and the queue item together
Our global replication system is built on the back of this queue, meaning that you can list objects anywhere in any region and you will get the same view of your bucket in every region. This is all driven by our queue.
When a user does a read on an object and there isn't a copy of it locally, this async queueing system automatically kicks in to make sure that the data is copied over so it's hot and ready for next time. Future reads can just happen from the cache on that particular region.
Conclusion
FoundationDB is more than just our metadata storage layer, it's the foundation to the Tigris platform. All objects, indices, and tasks use FoundationDB as the bedrock for storage. This lets us have data propagate everywhere in the world without having to build a multi-region FoundationDB cluster or add an expensive second coordination system into our stack. Every region has their own FoundationDB clusters that are all kept in sync automatically.
Storing metadata, indices, and task queues in the same database lets us focus more of our time on delivering users global object storage and less of our time fiddling with the details on how to make Kafka performant. Without FoundationDB we would not have the primitives we need to make Tigris happen.
And that's it, thank you!
Further reading
- Skipping the boring parts of building a storage platform using FoundationDB — why we didn't build our own distributed transaction layer.
- Tigris metadata layer on FoundationDB — the key encoding, integer ID compression, and value format in detail.
- Backing up FoundationDB